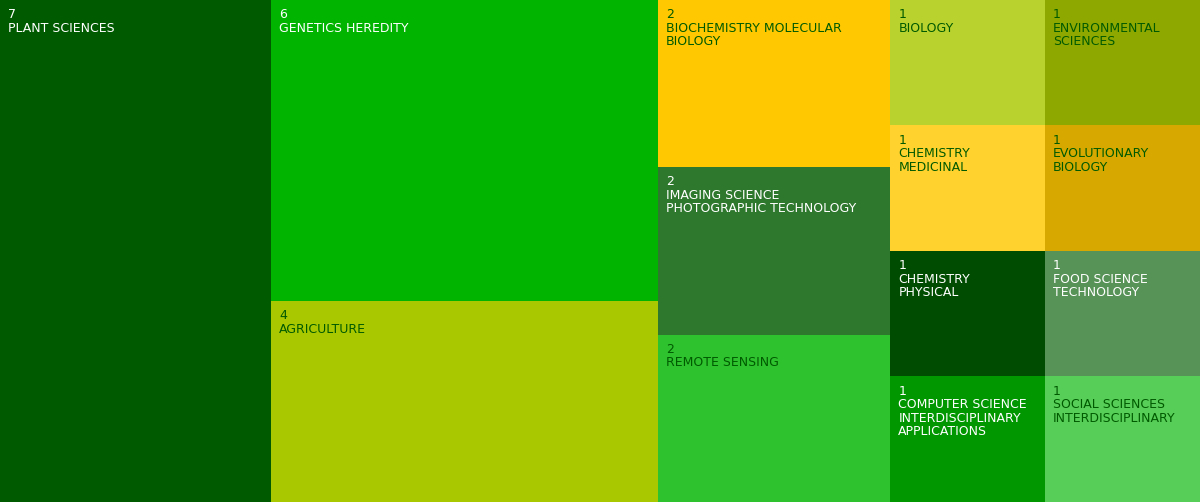
Devasahayam, Bennet Rohan Fernando; McNeil, Thomas; Wubet, Tesfaye; Schmutzer, Thomas Nanopore sequencing reveals coordinated host and microbiome responses across barley genotypes Artikel In: BMC Biology, Bd. 24, Nr. 1, S. 177, 2026. @article{devasahayam2026nanopore,
title = {Nanopore sequencing reveals coordinated host and microbiome responses across barley genotypes},
author = {Bennet Rohan Fernando Devasahayam and Thomas McNeil and Tesfaye Wubet and Thomas Schmutzer},
doi = {10.1186/s12915-026-02688-3},
year = {2026},
date = {2026-07-29},
urldate = {2026-07-29},
journal = {BMC Biology},
volume = {24},
number = {1},
pages = {177},
abstract = {BackgroundBarley (Hordeum vulgare L.) provides a suitable model for studying domestication-driven plant-microbiome interactions. Although wild, landrace, and modern genotypes host distinct rhizosphere communities, the extent to which roots and microbes reciprocally influence each other remains unclear. Here, we applied an integrated multi-omics approach combining long-read metagenomics, root transcriptomics, and plant genomics to understand genotype-specific host-microbiome coordination.ResultsOxford Nanopore whole metagenome sequencing (WMS) revealed genotype-associated shifts in rhizosphere communities across seasons. Functional profiling showed a conserved metabolic backbone including amino acid metabolism, energy production, and secondary metabolite biosynthesis, alongside genotype-dependent variation in carbohydrate metabolism and transport-associated pathways. Genome-resolved analysis through metagenome-assembled genomes (MAGs) further detailed the taxonomic and functional architecture of key rhizosphere lineages. Root transcriptome profiling identified extensive differential expression associated with microbial perception, signaling, defense, and metabolic processes. Integration of host and microbiome data revealed coordinated molecular patterns, indicating that barley genotypes are associated with distinct microbial assemblages and corresponding transcriptional responses.ConclusionsThese findings indicate that domestication has shaped coordinated associations between barley genotypes and their rhizosphere microbiomes, reflected in both microbial community composition and host transcriptional regulation. This work provides new insights into the evolutionary tuning of plant-microbiome relationships and highlights opportunities for microbiome-informed strategies in barley improvement.},
keywords = {DiP-DIAMANT, Host-microbiome interactions, Long-read nanopore sequencing, Metagenomics, Rhizosphere microbiome, Transcriptomics},
pubstate = {published},
tppubtype = {article}
}
BackgroundBarley (Hordeum vulgare L.) provides a suitable model for studying domestication-driven plant-microbiome interactions. Although wild, landrace, and modern genotypes host distinct rhizosphere communities, the extent to which roots and microbes reciprocally influence each other remains unclear. Here, we applied an integrated multi-omics approach combining long-read metagenomics, root transcriptomics, and plant genomics to understand genotype-specific host-microbiome coordination.ResultsOxford Nanopore whole metagenome sequencing (WMS) revealed genotype-associated shifts in rhizosphere communities across seasons. Functional profiling showed a conserved metabolic backbone including amino acid metabolism, energy production, and secondary metabolite biosynthesis, alongside genotype-dependent variation in carbohydrate metabolism and transport-associated pathways. Genome-resolved analysis through metagenome-assembled genomes (MAGs) further detailed the taxonomic and functional architecture of key rhizosphere lineages. Root transcriptome profiling identified extensive differential expression associated with microbial perception, signaling, defense, and metabolic processes. Integration of host and microbiome data revealed coordinated molecular patterns, indicating that barley genotypes are associated with distinct microbial assemblages and corresponding transcriptional responses.ConclusionsThese findings indicate that domestication has shaped coordinated associations between barley genotypes and their rhizosphere microbiomes, reflected in both microbial community composition and host transcriptional regulation. This work provides new insights into the evolutionary tuning of plant-microbiome relationships and highlights opportunities for microbiome-informed strategies in barley improvement. |
Pöhlitz, Julia Nachhaltige Nutzung von Feldrainen für klimaresiliente Agrarökosysteme in Süd-Sachsen-Anhalt - FaiReSyst Buchkapitel In: Agroforst - vielfältig gestalten - zukunftsfährig nutzen | Bund Heimat und Umwelt in Deutschland (BHU) - Bundesverband für Kultur, Natur und Heimat e. V. (Hrsg.): Bund Heimat und Umwelt in Deutschland, Bonn, 2026, ISBN: 978-3-910753-09-9. @inbook{buh000,
title = {Nachhaltige Nutzung von Feldrainen f\"{u}r klimaresiliente Agrar\"{o}kosysteme in S\"{u}d-Sachsen-Anhalt - FaiReSyst},
author = {Julia P\"{o}hlitz},
editor = {Agroforst - vielf\"{a}ltig gestalten - zukunftsf\"{a}hrig nutzen | Bund Heimat und Umwelt in Deutschland (BHU) - Bundesverband f\"{u}r Kultur, Natur und Heimat e. V.},
url = {https://bhu.de/de/publikationen/},
isbn = {978-3-910753-09-9},
year = {2026},
date = {2026-07-09},
urldate = {2026-07-09},
publisher = {Bund Heimat und Umwelt in Deutschland, Bonn},
keywords = {DiP-FaiReSyst},
pubstate = {published},
tppubtype = {inbook}
}
|
Conrad, Christopher; Schreiner, Vera; Renkel, Jonathan; Wenzel, Jan-Lukas Agroforst für eine klimaresiliente, attraktive und ökonomisch nachhaltige Agrarlandschaft in Mitteldeutschland - Die Projektidee DiP-SMART Agroforst Buchkapitel In: Agroforst - vielfältig gestalten - zukunftsfährig nutzen | Bund Heimat und Umwelt in Deutschland (BHU) - Bundesverband für Kultur, Natur und Heimat e. V. (Hrsg.): Bund Heimat und Umwelt in Deutschland, Bonn, 2026, ISBN: 978-3-910753-09-9. @inbook{buh001,
title = {Agroforst f\"{u}r eine klimaresiliente, attraktive und \"{o}konomisch nachhaltige Agrarlandschaft in Mitteldeutschland - Die Projektidee DiP-SMART Agroforst},
author = {Christopher Conrad and Vera Schreiner and Jonathan Renkel and Jan-Lukas Wenzel},
editor = {Agroforst - vielf\"{a}ltig gestalten - zukunftsf\"{a}hrig nutzen | Bund Heimat und Umwelt in Deutschland (BHU) - Bundesverband f\"{u}r Kultur, Natur und Heimat e. V.},
url = {https://bhu.de/de/publikationen/},
isbn = {978-3-910753-09-9},
year = {2026},
date = {2026-07-09},
publisher = {Bund Heimat und Umwelt in Deutschland, Bonn},
keywords = {DiP-SMART Agroforst},
pubstate = {published},
tppubtype = {inbook}
}
|
Kalmer, Theresa Sachsen-Anhalt will mit der Erbse neue Wertschöpfungsketten schaffen Sonstige 2026. @misc{topagra_001,
title = {Sachsen-Anhalt will mit der Erbse neue Wertsch\"{o}pfungsketten schaffen },
author = {Theresa Kalmer },
url = {https://www.topagrar.com/acker/news/sachsen-anhalt-will-mit-der-erbse-den-strukturwandel-vorantreiben-20026526.html},
year = {2026},
date = {2026-06-23},
abstract = {Forscher und Unternehmen in Sachsen-Anhalt bauen den Anbau von Erbsen aus und entwickeln neue Produkte f\"{u}r den wachsenden Markt pflanzlicher Lebensmittel.},
keywords = {DiP-DiPisum, Presse},
pubstate = {published},
tppubtype = {misc}
}
Forscher und Unternehmen in Sachsen-Anhalt bauen den Anbau von Erbsen aus und entwickeln neue Produkte für den wachsenden Markt pflanzlicher Lebensmittel. |
Josling, Daniel Schnitzel vom Erbsenacker Sonstige 2026. @misc{MZ2026-06-22,
title = {Schnitzel vom Erbsenacker},
author = {Daniel Josling},
url = {https://www.mz.de/panorama/wie-die-erbse-zum-wirtschaftsfaktor-werden-konnte-4270930},
year = {2026},
date = {2026-06-22},
urldate = {2026-06-22},
abstract = {Pflanzliche Proteine stecken inzwischen in vielen Fleisch- und Milchersatzprodukten. Forscher und Unternehmen sehen darin Chancen f\"{u}r neue Arbeitspl\"{a}tze und Wertsch\"{o}pfung im Land.},
keywords = {DiP-DiPisum, Presse},
pubstate = {published},
tppubtype = {misc}
}
Pflanzliche Proteine stecken inzwischen in vielen Fleisch- und Milchersatzprodukten. Forscher und Unternehmen sehen darin Chancen für neue Arbeitsplätze und Wertschöpfung im Land. |
dpa, Sachsen Wie die Erbse zum Wirtschaftsfaktor werden könnte Sonstige 2026. @misc{dpa_001,
title = {Wie die Erbse zum Wirtschaftsfaktor werden k\"{o}nnte},
author = {dpa, Sachsen},
url = {https://www.zeit.de/news/2026-06/20/wie-die-erbse-zum-wirtschaftsfaktor-werden-koennte},
year = {2026},
date = {2026-06-20},
urldate = {2026-06-20},
abstract = {Vegetarische Schnitzel, pflanzliche Milchalternativen oder Proteinriegel: Produkte auf Basis von Erbsenprotein finden sich inzwischen in vielen Supermarktregalen. Forschende und Unternehmen in Sachsen-Anhalt sehen darin eine wirtschaftliche Chance f\"{u}r das Land. Sie arbeiten daran, den Erbsenanbau auszubauen und neue Wertsch\"{o}pfungsketten rund um pflanzliche Proteine aufzubauen. },
keywords = {DiP-DiPisum, Presse},
pubstate = {published},
tppubtype = {misc}
}
Vegetarische Schnitzel, pflanzliche Milchalternativen oder Proteinriegel: Produkte auf Basis von Erbsenprotein finden sich inzwischen in vielen Supermarktregalen. Forschende und Unternehmen in Sachsen-Anhalt sehen darin eine wirtschaftliche Chance für das Land. Sie arbeiten daran, den Erbsenanbau auszubauen und neue Wertschöpfungsketten rund um pflanzliche Proteine aufzubauen. |
Low, Johannes; Conrad, Christopher; Hill, Steven; Thiel, Michael; Ullmann, Tobias; Otte, Insa A novel approach to assessing the tracking accuracy of crop phenology for multi-orbit and multi-feature Sentinel-1 time series Artikel In: SCIENCE OF REMOTE SENSING, Bd. 13, 2026, ISSN: 2666-0172. @article{WOS:001673578400001,
title = {A novel approach to assessing the tracking accuracy of crop phenology for multi-orbit and multi-feature Sentinel-1 time series},
author = {Johannes Low and Christopher Conrad and Steven Hill and Michael Thiel and Tobias Ullmann and Insa Otte},
doi = {10.1016/j.srs.2026.100370},
issn = {2666-0172},
year = {2026},
date = {2026-06-01},
urldate = {2026-06-01},
journal = {SCIENCE OF REMOTE SENSING},
volume = {13},
keywords = {Canola, DEMMIN, DiP-ZAZIkI, InSAR coherence, Phenology, Sugar beet, Wheat},
pubstate = {published},
tppubtype = {article}
}
|
Klima, Johanna Wie KI und neue Anbaumethoden die Zuckerrübe retten sollen Sonstige 2026. @misc{bzeitung001,
title = {Wie KI und neue Anbaumethoden die Zuckerr\"{u}be retten sollen},
author = {Johanna Klima},
url = {https://www.bauernzeitung.de/regional/sachsen-anhalt/ki-neue-anbaumethoden-zuckerruebe-retten-1211},
year = {2026},
date = {2026-05-19},
abstract = {Die Klimakrise setzt dem Zuckerr\"{u}benanbau in Sachsen-Anhalt zunehmend zu: trockene B\"{o}den, h\"{a}ufigere Extremwetterlagen und steigende Kosten belasten viele Betriebe. Forschende testen deshalb neue Anbaumethoden, die Wasser sparen und Ertr\"{a}ge stabilisieren sollen. Mithilfe von KI, Drohnen und Satellitendaten wollen sie herausfinden, wie die Zuckerr\"{u}be auch unter schwierigen Bedingungen wirtschaftlich bleiben kann. },
keywords = {DiP-ZAZIkI, Presse},
pubstate = {published},
tppubtype = {misc}
}
Die Klimakrise setzt dem Zuckerrübenanbau in Sachsen-Anhalt zunehmend zu: trockene Böden, häufigere Extremwetterlagen und steigende Kosten belasten viele Betriebe. Forschende testen deshalb neue Anbaumethoden, die Wasser sparen und Erträge stabilisieren sollen. Mithilfe von KI, Drohnen und Satellitendaten wollen sie herausfinden, wie die Zuckerrübe auch unter schwierigen Bedingungen wirtschaftlich bleiben kann. |
Maydell, Daniel; Schwerdt, Johannes; Lehnert, Heike; Pöschl-Grau, Yvonne; Schmutzer, Thomas; Marthe, Frank Population structure, genetic diversity and core set construction of an international collection of 256 Melissa officinalis genotypes Artikel In: BMC Plant Biology, Bd. 26, Nr. 1, S. 794, 2026, ISSN: 1471-2229. @article{vonmaydell2026population,
title = {Population structure, genetic diversity and core set construction of an international collection of 256 Melissa officinalis genotypes},
author = {Daniel Maydell and Johannes Schwerdt and Heike Lehnert and Yvonne P\"{o}schl-Grau and Thomas Schmutzer and Frank Marthe},
doi = {10.1186/s12870-026-08853-8},
issn = {1471-2229},
year = {2026},
date = {2026-05-01},
urldate = {2026-05-01},
journal = {BMC Plant Biology},
volume = {26},
number = {1},
pages = {794},
abstract = {BackgroundMelissa officinalis (balm) is a perennial medicinal. Climate change and high cultivation costs necessitate the breeding of new cultivars with improved stress tolerance and high metabolite content. However, the high costs of phenotyping large collections limit breeding progress. This study characterized the genetic diversity and population structure of 256 genotypes from 215 international accessions using flow cytometry and genotyping by sequencing (GBS). The primary objective was to identify untapped genetic resources and establish core sets to streamline future breeding and research efforts.ResultsMorphological characterization and flow cytometry revealed a clear division by ploidy and subspecies. The collection comprised 209 diploid and three polyploid genotypes of ssp. officinalis (2C = 1.79 pg) and 44 tetraploid genotypes of ssp. altissima (4C = 3.57 pg). GBS generated 29,307 and 9,909 SNPs for the entire collection and a subset of ssp. officinalis genotypes, respectively. We identified significant genetic differentiation between the subspecies, as confirmed by PCA (PC1 = 69.9%), STRUCTURE, and hierarchical clustering. With 21,770 private alleles and HE = 0.38 subspecies altissima exhibited greater genetic divergence than ssp. officinalis (2,953 private alleles},
keywords = {DiP-DIAMANT, DiP-OptiLamia, Domestication, Gene flow, Gene pool, Genetic diversity, Identification (biology), Melissa officinalis, Officinalis, Population, Subspecies},
pubstate = {published},
tppubtype = {article}
}
BackgroundMelissa officinalis (balm) is a perennial medicinal. Climate change and high cultivation costs necessitate the breeding of new cultivars with improved stress tolerance and high metabolite content. However, the high costs of phenotyping large collections limit breeding progress. This study characterized the genetic diversity and population structure of 256 genotypes from 215 international accessions using flow cytometry and genotyping by sequencing (GBS). The primary objective was to identify untapped genetic resources and establish core sets to streamline future breeding and research efforts.ResultsMorphological characterization and flow cytometry revealed a clear division by ploidy and subspecies. The collection comprised 209 diploid and three polyploid genotypes of ssp. officinalis (2C = 1.79 pg) and 44 tetraploid genotypes of ssp. altissima (4C = 3.57 pg). GBS generated 29,307 and 9,909 SNPs for the entire collection and a subset of ssp. officinalis genotypes, respectively. We identified significant genetic differentiation between the subspecies, as confirmed by PCA (PC1 = 69.9%), STRUCTURE, and hierarchical clustering. With 21,770 private alleles and HE = 0.38 subspecies altissima exhibited greater genetic divergence than ssp. officinalis (2,953 private alleles |
Hilgardt, Christiane Pflanzenzüchtung schneller machen mit digitaler Präzisionsgenomik Sonstige 2026. @misc{Presse009,
title = {Pflanzenz\"{u}chtung schneller machen mit digitaler Pr\"{a}zisionsgenomik},
author = {Christiane Hilgardt},
url = {https://biooekonomie.de/foerderung/foerderbeispiele/pflanzenzuechtung-schneller-machen-mit-digitaler-praezisionsgenomik},
year = {2026},
date = {2026-04-27},
urldate = {2026-04-27},
abstract = {Wie lassen sich neue Pflanzensorten schneller entwickeln? Das Projekt DiP-DIAMANT setzt auf digitale Pr\"{a}zisionsgenomik: Moderne Sequenzierung und k\"{u}nstliche Intelligenz helfen dabei, gro\sse Mengen genetischer Daten auszuwerten und so die Pflanzenz\"{u}chtung deutlich zu beschleunigen.
},
keywords = {DiP-DIAMANT, Presse},
pubstate = {published},
tppubtype = {misc}
}
Wie lassen sich neue Pflanzensorten schneller entwickeln? Das Projekt DiP-DIAMANT setzt auf digitale Präzisionsgenomik: Moderne Sequenzierung und künstliche Intelligenz helfen dabei, große Mengen genetischer Daten auszuwerten und so die Pflanzenzüchtung deutlich zu beschleunigen.
|
Worzewski, Tamara Wir sind eine kleine Gruppe mit großen Fragestellungen Sonstige 2026. @misc{Presse008,
title = {Wir sind eine kleine Gruppe mit gro\ssen Fragestellungen},
author = {Worzewski, Tamara},
url = {https://biooekonomie.de/akteure/interviews/wir-sind-eine-kleine-gruppe-mit-grossen-fragestellungen},
year = {2026},
date = {2026-04-13},
urldate = {2026-04-13},
abstract = {Als Spezialist f\"{u}r Long-Read-Genomik und KI in Pflanzenz\"{u}chtung leitet Thomas Schmutzer das Projekt DiP-DIAMANT. Das Akronym \textbf{DIAMANT} suchte er wegen der pr\"{a}zisen Sch\"{a}rfe aus, es steht n\"{a}mlich f\"{u}r \textbf{Di}gitale \textbf{M}ethoden f\"{u}r \textbf{A}ngewandte Pr\"{a}zisionsgenomik, \textbf{N}etzwerkanalyse und \textbf{T}echnologieentwicklung. Was das bedeutet, erkl\"{a}rt er im Interview.},
keywords = {DiP-DIAMANT, Presse},
pubstate = {published},
tppubtype = {misc}
}
Als Spezialist für Long-Read-Genomik und KI in Pflanzenzüchtung leitet Thomas Schmutzer das Projekt DiP-DIAMANT. Das Akronym DIAMANT suchte er wegen der präzisen Schärfe aus, es steht nämlich für Digitale Methoden für Angewandte Präzisionsgenomik, Netzwerkanalyse und Technologieentwicklung. Was das bedeutet, erklärt er im Interview. |
Fierlej, Yannick; Grazer, Laurine; Khaled, Abdelsabour G. A.; Langer, Matthias; Montes, Émilie; Perez, Thibaut; Gallo, Laura; Lacombe, Benoît; Nacry, Philippe; Duplus-Bottin, Hélène; Doll, Nicolas M.; Borisjuk, Ljudmilla; Rolletschek, Hardy; Ingram, Gwyneth; Rogowsky, Peter M.; Widiez, Thomas ZmSWEET Sucrose transporters expressed in the endosperm adjacent to the maize embryo are necessary for carbon partitioning and embryo growth [Preprint] Artikel In: bioRxiv, 2026. @article{fierlej2026zmsweet,
title = {ZmSWEET Sucrose transporters expressed in the endosperm adjacent to the maize embryo are necessary for carbon partitioning and embryo growth [Preprint]},
author = {Yannick Fierlej and Laurine Grazer and Abdelsabour G. A. Khaled and Matthias Langer and \'{E}milie Montes and Thibaut Perez and Laura Gallo and Beno\^{i}t Lacombe and Philippe Nacry and H\'{e}l\`{e}ne Duplus-Bottin and Nicolas M. Doll and Ljudmilla Borisjuk and Hardy Rolletschek and Gwyneth Ingram and Peter M. Rogowsky and Thomas Widiez},
doi = {10.64898/2026.02.24.707659},
year = {2026},
date = {2026-02-25},
urldate = {2026-02-25},
journal = {bioRxiv},
publisher = {Cold Spring Harbor Laboratory},
abstract = {Abstract In cereals such as maize, the kernel accumulates large quantities of storage compounds, including carbohydrates, lipids, and proteins, a process that requires tight regulation of nutrient transport. Seeds are composed of distinct tissues: the embryo, the endosperm, and maternal tissues that are symplastically isolated (not connected through plasmodesmata), necessitating specialized nutrient transfer mechanisms. In maize, nutrient transfer from maternal tissues to the endosperm via specialized basal endosperm transfer layer (BETL) cells is well characterized. However, nutrient transfer at the endosperm/embryo interface remains poorly understood. Consequently, the routes by which maternal carbon-derived sugars support embryo growth are still unclear. Our previous transcriptomic profiling uncovered a novel Endosperm domain Adjacent to the embryo Scutellum (EAS) with strong enrichment for transporter genes. Notably, genes encoding three sugar transporters from the SWEET (Sugars Will Eventually be Exported Transporters) family are highly and preferentially expressed in the EAS, suggesting the existence of a specialized sugar transfer mechanism at this interface. We show that the ZmSWEET proteins encoded by these genes are membrane-localized sucrose transporters and are functionally important for kernel development. A gene-edited triple zmsweet14a/14b/15a knock-out mutant exhibits reduced kernel weight and embryo size, significantly decreased embryo oil accumulation at maturity, and altered carbon partitioning within the kernel. In addition to these defects, mutant kernels display a significant reduction in primary root length during germination, indicating either lasting physiological consequences of disrupted sucrose transport during seed development or an additional role for these SWEET transporters during germination. Together, our findings demonstrate that sucrose transport at the endosperm/embryo interface is critical for proper carbon allocation, embryo development, and seed vigor, and identify the EAS as a key functional domain and potential target for improving seed composition.},
keywords = {DiP-Magdi, EAS, Embryo, Endosperm, Mutant, Scutellum, Sucrose, Transporter},
pubstate = {published},
tppubtype = {article}
}
Abstract In cereals such as maize, the kernel accumulates large quantities of storage compounds, including carbohydrates, lipids, and proteins, a process that requires tight regulation of nutrient transport. Seeds are composed of distinct tissues: the embryo, the endosperm, and maternal tissues that are symplastically isolated (not connected through plasmodesmata), necessitating specialized nutrient transfer mechanisms. In maize, nutrient transfer from maternal tissues to the endosperm via specialized basal endosperm transfer layer (BETL) cells is well characterized. However, nutrient transfer at the endosperm/embryo interface remains poorly understood. Consequently, the routes by which maternal carbon-derived sugars support embryo growth are still unclear. Our previous transcriptomic profiling uncovered a novel Endosperm domain Adjacent to the embryo Scutellum (EAS) with strong enrichment for transporter genes. Notably, genes encoding three sugar transporters from the SWEET (Sugars Will Eventually be Exported Transporters) family are highly and preferentially expressed in the EAS, suggesting the existence of a specialized sugar transfer mechanism at this interface. We show that the ZmSWEET proteins encoded by these genes are membrane-localized sucrose transporters and are functionally important for kernel development. A gene-edited triple zmsweet14a/14b/15a knock-out mutant exhibits reduced kernel weight and embryo size, significantly decreased embryo oil accumulation at maturity, and altered carbon partitioning within the kernel. In addition to these defects, mutant kernels display a significant reduction in primary root length during germination, indicating either lasting physiological consequences of disrupted sucrose transport during seed development or an additional role for these SWEET transporters during germination. Together, our findings demonstrate that sucrose transport at the endosperm/embryo interface is critical for proper carbon allocation, embryo development, and seed vigor, and identify the EAS as a key functional domain and potential target for improving seed composition. |
Uphoff, Riko Corwin; Schuler, Steffen; Grosse, Ivo; Muller-Hannemann, Matthias Fast barcode calling based on k-mer distances Artikel In: PNAS NEXUS, Bd. 5, Nr. 2, 2026. @article{WOS:001681509300001,
title = {Fast barcode calling based on k-mer distances},
author = {Riko Corwin Uphoff and Steffen Schuler and Ivo Grosse and Matthias Muller-Hannemann},
doi = {10.1093/pnasnexus/pgag001},
year = {2026},
date = {2026-02-01},
urldate = {2026-02-01},
journal = {PNAS NEXUS},
volume = {5},
number = {2},
keywords = {Algorithm engineering, DiP-Hyperspace, DNA barcode calling, Spatial transcriptomics},
pubstate = {published},
tppubtype = {article}
}
|
Westermann, Thisbe Agrarmesse in Berlin: Das sind Halles Aushängeschilder bei der Grünen Woche Sonstige 2026. @misc{Westermann2026,
title = {Agrarmesse in Berlin: Das sind Halles Aush\"{a}ngeschilder bei der Gr\"{u}nen Woche},
author = {Thisbe Westermann},
url = {https://www.mz.de/lokal/halle-saale/das-sind-halles-aushangeschilder-bei-der-grunen-woche-4184999},
year = {2026},
date = {2026-01-21},
urldate = {2026-01-21},
journal = {xxx},
volume = {001},
number = {2},
issue = {1},
keywords = {DiP-Verbund, Presse},
pubstate = {published},
tppubtype = {misc}
}
|
Moorhoff, Felix; Zhang, Yanzi; Qiu, Sizhe; Dong, Wenjuan; Medina-Ortiz, David; Zhao, Jing; Davari, Mehdi D. Machine Learning-Driven Enzyme Mining: Opportunities, Challenges, and Future Perspectives Artikel In: ACS CATALYSIS, Bd. 16, Nr. 1, S. 12-30, 2026, ISSN: 2155-5435. @article{WOS:001643722100001,
title = {Machine Learning-Driven Enzyme Mining: Opportunities, Challenges, and Future Perspectives},
author = {Felix Moorhoff and Yanzi Zhang and Sizhe Qiu and Wenjuan Dong and David Medina-Ortiz and Jing Zhao and Mehdi D. Davari},
doi = {10.1021/acscatal.5c04814},
issn = {2155-5435},
year = {2026},
date = {2026-01-01},
urldate = {2026-01-01},
journal = {ACS CATALYSIS},
volume = {16},
number = {1},
pages = {12-30},
keywords = {Biocatalysis, DiP-BioCasNavi, Enzyme discovery, Machine learning},
pubstate = {published},
tppubtype = {article}
}
|
Spanner, Rebecca; Sallam, Ahmad H.; Guo, Yu; Jayakodi, Murukarthick; Himmelbach, Axel; Fiebig, Anne; Simmons, Jamie; Bethke, Gerit; Lee, Yoonjung; Arge, Luis Willian Pacheco; Qiu, Yinjie; Badea, Ana; Baum, Michael; Belzile, Francois; Ben-David, Roi; Brueggeman, Robert; Case, Austin; Cattivelli, Luigi; Davis, Michael; Dockter, Christoph; Dolezel, Jaroslav; Dreiseitl, Antonin; Gavin, Ryan; Glick, Lior; Greiner, Stephan; Hamilton, Ruth; Hayes, Patrick M.; Heisel, Scott; Henson, Cynthia; Kilian, Benjamin; Komatsuda, Takao; Li, Chengdao; Liu, Cheng; Mahalingam, Ramamurthy; Maruschewski, Maren; Matny, Oadi; Maurer, Andreas; Mayer, Klaus F. X.; Mayrose, Itay; Moscou, Matthew; Muehlbauer, Gary J.; Oono, Youko; Ordon, Frank; Ozkan, Hakan; Pecinka, Ales; Perovic, Dragan; Pillen, Klaus; Pourkheirandish, Mohammad; Russell, Joanne; Safar, Jan; Salvi, Silvio; Sanchez-Garcia, Miguel; Sato, Kazuhiro; Schmutzer, Thomas; Scholz, Uwe; Scott, Jeness; Brar, Gurcharn Singh; Smith, Kevin P.; Sorrells, Mark E.; Spannagl, Manuel; Stein, Nils; Tondelli, Alessandro; Tuberosa, Roberto; Tucker, James; Turkington, Thomas; Valkoun, Jan; Verma, Ramesh Pal Singh; Vinje, Marcus A.; Korff, Maria; Walling, Jason G.; Waugh, Robbie; Wise, Roger P.; Wulff, Brande B. H.; Yang, Shengming; Zhang, Guoping; Morrell, Peter L.; Mascher, Martin; Steffenson, Brian J. Whole-genome resequencing of the wild barley diversity collection: a resource for identifying and exploiting genetic variation for cultivated barley improvement Artikel In: G3-GENES GENOMES GENETICS, Bd. 16, Nr. 1, 2026, ISSN: 2160-1836. @article{WOS:001631204600001,
title = {Whole-genome resequencing of the wild barley diversity collection: a resource for identifying and exploiting genetic variation for cultivated barley improvement},
author = {Rebecca Spanner and Ahmad H. Sallam and Yu Guo and Murukarthick Jayakodi and Axel Himmelbach and Anne Fiebig and Jamie Simmons and Gerit Bethke and Yoonjung Lee and Luis Willian Pacheco Arge and Yinjie Qiu and Ana Badea and Michael Baum and Francois Belzile and Roi Ben-David and Robert Brueggeman and Austin Case and Luigi Cattivelli and Michael Davis and Christoph Dockter and Jaroslav Dolezel and Antonin Dreiseitl and Ryan Gavin and Lior Glick and Stephan Greiner and Ruth Hamilton and Patrick M. Hayes and Scott Heisel and Cynthia Henson and Benjamin Kilian and Takao Komatsuda and Chengdao Li and Cheng Liu and Ramamurthy Mahalingam and Maren Maruschewski and Oadi Matny and Andreas Maurer and Klaus F. X. Mayer and Itay Mayrose and Matthew Moscou and Gary J. Muehlbauer and Youko Oono and Frank Ordon and Hakan Ozkan and Ales Pecinka and Dragan Perovic and Klaus Pillen and Mohammad Pourkheirandish and Joanne Russell and Jan Safar and Silvio Salvi and Miguel Sanchez-Garcia and Kazuhiro Sato and Thomas Schmutzer and Uwe Scholz and Jeness Scott and Gurcharn Singh Brar and Kevin P. Smith and Mark E. Sorrells and Manuel Spannagl and Nils Stein and Alessandro Tondelli and Roberto Tuberosa and James Tucker and Thomas Turkington and Jan Valkoun and Ramesh Pal Singh Verma and Marcus A. Vinje and Maria Korff and Jason G. Walling and Robbie Waugh and Roger P. Wise and Brande B. H. Wulff and Shengming Yang and Guoping Zhang and Peter L. Morrell and Martin Mascher and Brian J. Steffenson},
doi = {10.1093/g3journal/jkaf261},
issn = {2160-1836},
year = {2026},
date = {2026-01-01},
urldate = {2026-01-01},
journal = {G3-GENES GENOMES GENETICS},
volume = {16},
number = {1},
abstract = {To exploit allelic variation in Hordeum vulgare subsp. spontaneum, the
Wild Barley Diversity Collection was subjected to paired-end Illumina
sequencing at similar to 9 x depth and evaluated for several agronomic
traits. We discovered 240.2 million single nucleotide polymorphisms
(SNPs) after alignment to the Morex V3 assembly and 24.4 million short
(1 to 50 bp) insertions and deletions. A genome-wide association study
of lemma color identified one marker-trait association (MTA) on
chromosome 1H close to HvBlp, the cloned gene controlling black lemma.
Four MTAs were identified for seedling stem rust resistance, including 2
novel loci on chromosomes 1H and 6H and one co-locating to the complex
RMRL1-RMRL2 locus on 5H. The whole-genome sequence data described herein
will facilitate the identification and utilization of new alleles for
barley improvement.},
keywords = {Genomic data, Sequencing, Variant analysis},
pubstate = {published},
tppubtype = {article}
}
To exploit allelic variation in Hordeum vulgare subsp. spontaneum, the
Wild Barley Diversity Collection was subjected to paired-end Illumina
sequencing at similar to 9 x depth and evaluated for several agronomic
traits. We discovered 240.2 million single nucleotide polymorphisms
(SNPs) after alignment to the Morex V3 assembly and 24.4 million short
(1 to 50 bp) insertions and deletions. A genome-wide association study
of lemma color identified one marker-trait association (MTA) on
chromosome 1H close to HvBlp, the cloned gene controlling black lemma.
Four MTAs were identified for seedling stem rust resistance, including 2
novel loci on chromosomes 1H and 6H and one co-locating to the complex
RMRL1-RMRL2 locus on 5H. The whole-genome sequence data described herein
will facilitate the identification and utilization of new alleles for
barley improvement. |
Herrera-Rocha, Fabio; Medina-Ortiz, David; Wyrzykala, Desiree; Sudha, Tharun Srinivasan; Davari, Mehdi D. Multitask Bayesian Neural Networks for Multiparameter Protein Engineering [Preprint] Artikel In: arXiv, 2026. @article{herrerarocha2026multitask,
title = {Multitask Bayesian Neural Networks for Multiparameter Protein Engineering [Preprint]},
author = {Fabio Herrera-Rocha and David Medina-Ortiz and Desiree Wyrzykala and Tharun Srinivasan Sudha and Mehdi D. Davari},
doi = {10.48550/arxiv.2608.18604},
year = {2026},
date = {2026-01-01},
urldate = {2026-01-01},
journal = {arXiv},
publisher = {Cornell University},
abstract = {Simultaneously engineering multiple protein properties remains a major challenge. Existing machine learning-based pipelines for protein engineering often model properties separately, failing to capture their dependencies and trade-offs. Here, we systematically evaluate how Bayesian parameterization on Multitask Neural Networks can enable robust simultaneous protein engineering under scarce, noisy experimental data. We curated a comprehensive set of 27 multiparameter protein datasets. Then, we compared three algorithm architectures spanning low to full Bayesian parameterization across 16 sequence representations and dimensionality reduction (2,592 models). Bayesian Last Layer models delivered the strongest overall accuracy, generalization, and calibration, ranking as the top-performing model on 70% of benchmark datasets. Dimensionality reduction improved predictive performance by up to 42% and enhanced calibration up to 57% across architectures. Notably, simple One-Hot encoding achieved top performance on 25% of benchmark datasets, particularly with larger datasets. These results establish practical design principles for reliable and data-efficient multiparameter protein engineering.},
keywords = {Artificial neural network, Bayesian probability, Benchmark (surveying), Curse of dimensionality, Dimensionality reduction, DiP-BioCasNavi, DiP-LeFos, Feature engineering, Ranking (information retrieval), Set (abstract data type)},
pubstate = {published},
tppubtype = {article}
}
Simultaneously engineering multiple protein properties remains a major challenge. Existing machine learning-based pipelines for protein engineering often model properties separately, failing to capture their dependencies and trade-offs. Here, we systematically evaluate how Bayesian parameterization on Multitask Neural Networks can enable robust simultaneous protein engineering under scarce, noisy experimental data. We curated a comprehensive set of 27 multiparameter protein datasets. Then, we compared three algorithm architectures spanning low to full Bayesian parameterization across 16 sequence representations and dimensionality reduction (2,592 models). Bayesian Last Layer models delivered the strongest overall accuracy, generalization, and calibration, ranking as the top-performing model on 70% of benchmark datasets. Dimensionality reduction improved predictive performance by up to 42% and enhanced calibration up to 57% across architectures. Notably, simple One-Hot encoding achieved top performance on 25% of benchmark datasets, particularly with larger datasets. These results establish practical design principles for reliable and data-efficient multiparameter protein engineering. |
Fernández, Diego; García-Vinuesa, Julián Alfonso; Álvarez-Saravia, Diego; Soto-García, Michelle; Medina-Franco, José L.; Sepúlveda-Yáñez, Julieta; Cadet, Xavier F.; Cadet, Frédéric; Davari, Mehdi D.; Uribe-Paredes, Roberto; Herrera-Rocha, Fabio; Medina-Ortiz, David SilkRoute: A Descriptor-Driven Framework for Reproducible Multi-Source Biomolecular Data Acquisition [Preprint] Artikel In: bioRxiv, 2026. @article{fernandez2026silkroute,
title = {SilkRoute: A Descriptor-Driven Framework for Reproducible Multi-Source Biomolecular Data Acquisition [Preprint]},
author = {Diego Fern\'{a}ndez and Juli\'{a}n Alfonso Garc\'{i}a-Vinuesa and Diego \'{A}lvarez-Saravia and Michelle Soto-Garc\'{i}a and Jos\'{e} L. Medina-Franco and Julieta Sep\'{u}lveda-Y\'{a}\~{n}ez and Xavier F. Cadet and Fr\'{e}d\'{e}ric Cadet and Mehdi D. Davari and Roberto Uribe-Paredes and Fabio Herrera-Rocha and David Medina-Ortiz},
doi = {10.64898/2026.08.11.744100},
year = {2026},
date = {2026-01-01},
urldate = {2026-01-01},
journal = {bioRxiv},
publisher = {Cold Spring Harbor Laboratory},
abstract = {Abstract Background Biomolecular dataset construction often requires coordinated retrieval from heterogeneous repositories, identifier mapping, cross-reference enrichment, source-specific parsing, and provenance recording. These operations are frequently implemented through project-specific scripts, making acquisition procedures difficult to inspect, reproduce, or adapt across studies. We present SilkRoute, an open-source Python framework that formalizes biomolecular data acquisition as descriptor-defined, source-aware, and provenance-tracked workflows, providing a reproducible foundation for multi-source biomolecular dataset construction. Results SilkRoute uses machine-readable YAML descriptors to specify dataset intent, biomolecular modality, workflow mode, query logic, enrichment resources, execution parameters, and export settings. These descriptors drive a common execution model that coordinates primary retrieval and downstream enrichment while preserving source-specific outputs, interaction evidence when available, the original workflow configuration, metadata, and run summaries. We evaluated this model through three representative acquisition scenarios spanning proteins, compounds, and molecular interactions. In the protein-centered workflow, SilkRoute retrieved 2,444 reviewed antimicrobial protein records from UniProt and generated complementary outputs from AlphaFold DB, InterPro, Pathway Commons, and the Protein Data Bank. In the compound-centered workflow, a ChEMBL IC 50 query produced 1,445,939 activity records organized into query-defined potency ranges. In the interaction-centered workflow, 2,253 UniProt protein records were expanded with 902,713 BioGRID interaction records and 5,702 STRING interaction-partner records. Across these scenarios, the framework successfully applied the same descriptor-defined acquisition model to distinct biomolecular entity types, retrieval strategies, enrichment paths, and output structures. Conclusions SilkRoute extends beyond sequence retrieval by providing a reusable acquisition layer for constructing multi-source biomolecular datasets. By separating primary retrieval from enrichment and preserving source-aware outputs together with workflow descriptors and execution metadata, the framework makes acquisition procedures easier to inspect, reproduce, archive, and adapt. SilkRoute does not replace biological curation, label validation, deduplication, partitioning, or benchmarking, but provides structured and traceable acquisition packages that support these downstream processes.},
keywords = {chEMBL, Data acquisition, Data integration, Data retrieval, DiP-BioCasNavi, DiP-LeFos, Identifier, Interoperability, Python (programming language), UniProt, Workflow},
pubstate = {published},
tppubtype = {article}
}
Abstract Background Biomolecular dataset construction often requires coordinated retrieval from heterogeneous repositories, identifier mapping, cross-reference enrichment, source-specific parsing, and provenance recording. These operations are frequently implemented through project-specific scripts, making acquisition procedures difficult to inspect, reproduce, or adapt across studies. We present SilkRoute, an open-source Python framework that formalizes biomolecular data acquisition as descriptor-defined, source-aware, and provenance-tracked workflows, providing a reproducible foundation for multi-source biomolecular dataset construction. Results SilkRoute uses machine-readable YAML descriptors to specify dataset intent, biomolecular modality, workflow mode, query logic, enrichment resources, execution parameters, and export settings. These descriptors drive a common execution model that coordinates primary retrieval and downstream enrichment while preserving source-specific outputs, interaction evidence when available, the original workflow configuration, metadata, and run summaries. We evaluated this model through three representative acquisition scenarios spanning proteins, compounds, and molecular interactions. In the protein-centered workflow, SilkRoute retrieved 2,444 reviewed antimicrobial protein records from UniProt and generated complementary outputs from AlphaFold DB, InterPro, Pathway Commons, and the Protein Data Bank. In the compound-centered workflow, a ChEMBL IC 50 query produced 1,445,939 activity records organized into query-defined potency ranges. In the interaction-centered workflow, 2,253 UniProt protein records were expanded with 902,713 BioGRID interaction records and 5,702 STRING interaction-partner records. Across these scenarios, the framework successfully applied the same descriptor-defined acquisition model to distinct biomolecular entity types, retrieval strategies, enrichment paths, and output structures. Conclusions SilkRoute extends beyond sequence retrieval by providing a reusable acquisition layer for constructing multi-source biomolecular datasets. By separating primary retrieval from enrichment and preserving source-aware outputs together with workflow descriptors and execution metadata, the framework makes acquisition procedures easier to inspect, reproduce, archive, and adapt. SilkRoute does not replace biological curation, label validation, deduplication, partitioning, or benchmarking, but provides structured and traceable acquisition packages that support these downstream processes. |
Herrera-Rocha, Fabio; Medina-Ortiz, David; Mauz, Fabian; Pleiss, Juergen; Davari, Mehdi D. Best Practices for Machine Learning-Assisted Protein Engineering Artikel In: JOURNAL OF CHEMICAL INFORMATION AND MODELING, Bd. 65, Nr. 23, S. 12655-12667, 2025, ISSN: 1549-9596. @article{WOS:001616552400001,
title = {Best Practices for Machine Learning-Assisted Protein Engineering},
author = {Fabio Herrera-Rocha and David Medina-Ortiz and Fabian Mauz and Juergen Pleiss and Mehdi D. Davari},
doi = {10.1021/acs.jcim.5c01983},
issn = {1549-9596},
year = {2025},
date = {2025-12-01},
urldate = {2025-12-01},
journal = {JOURNAL OF CHEMICAL INFORMATION AND MODELING},
volume = {65},
number = {23},
pages = {12655-12667},
keywords = {DiP-LeFos, Machine learning, Optimization, Protein engineering},
pubstate = {published},
tppubtype = {article}
}
|
Borisjuk, Ljudmilla; Neuberger, Thomas; Rolletschek, Hardy Lipid MRI in plant science: principles and potential areas of application Artikel In: JOURNAL OF EXPERIMENTAL BOTANY, 2025, ISSN: 0022-0957. @article{WOS:001622101600001,
title = {Lipid MRI in plant science: principles and potential areas of application},
author = {Ljudmilla Borisjuk and Thomas Neuberger and Hardy Rolletschek},
doi = {10.1093/jxb/eraf479},
issn = {0022-0957},
year = {2025},
date = {2025-11-01},
urldate = {2025-11-01},
journal = {JOURNAL OF EXPERIMENTAL BOTANY},
keywords = {Artificial intelligence, DiP-Magdi, Lipid imaging, Magnetic resonance imaging, NMR spectroscopy, Phenotyping},
pubstate = {published},
tppubtype = {article}
}
|